At a glance
Task: classification | Headline: accuracy = 0.789
Summary
Project
Config-driven data science pipeline for high-fidelity industrial domains.
What was investigated
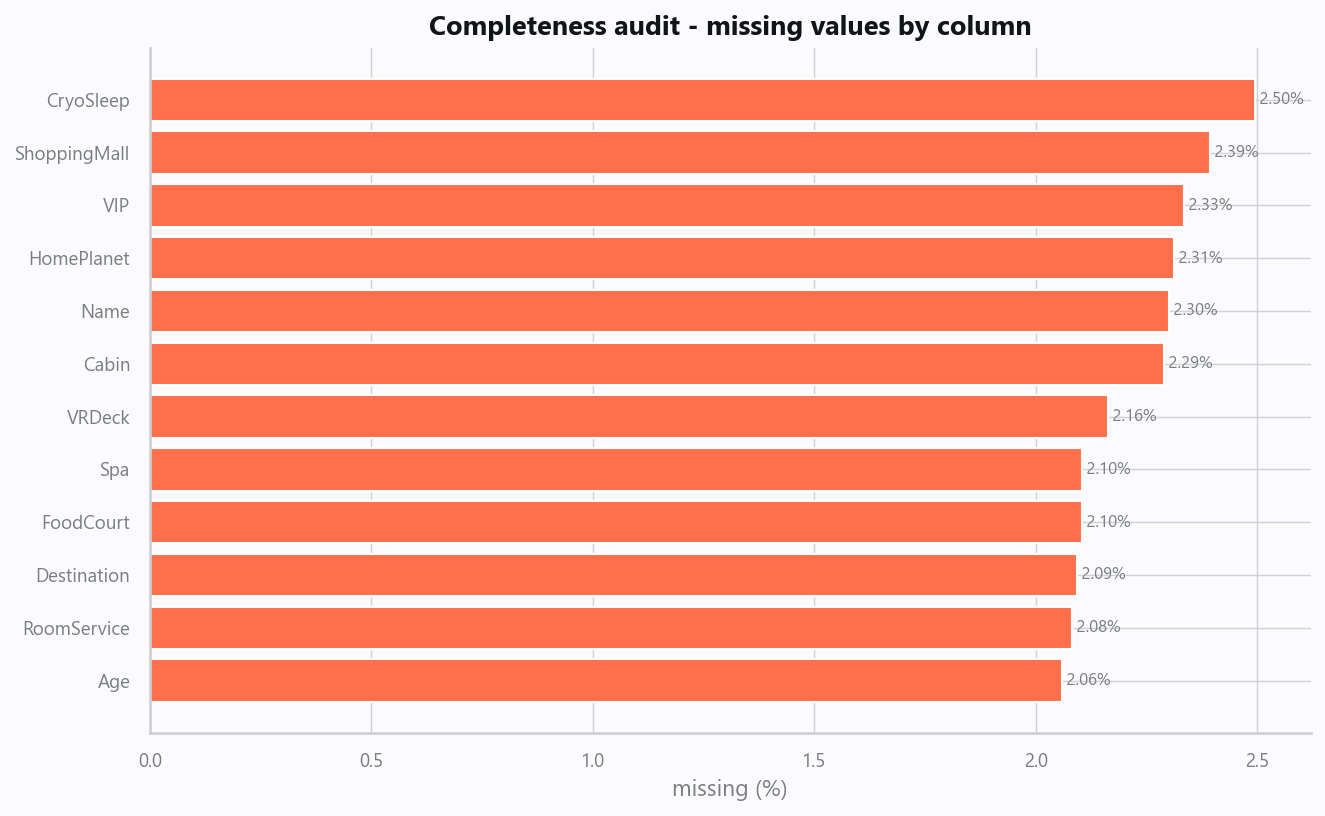
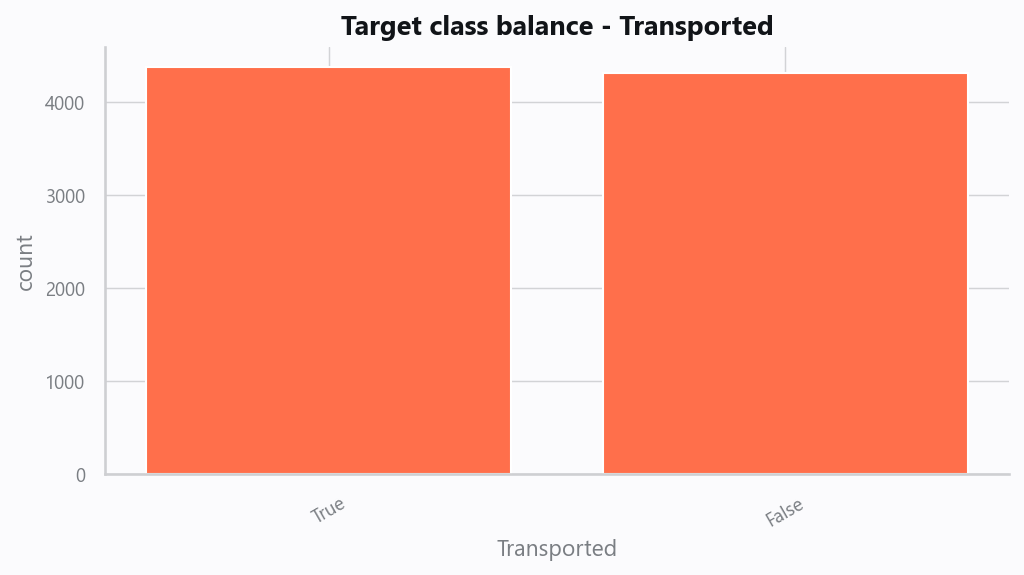
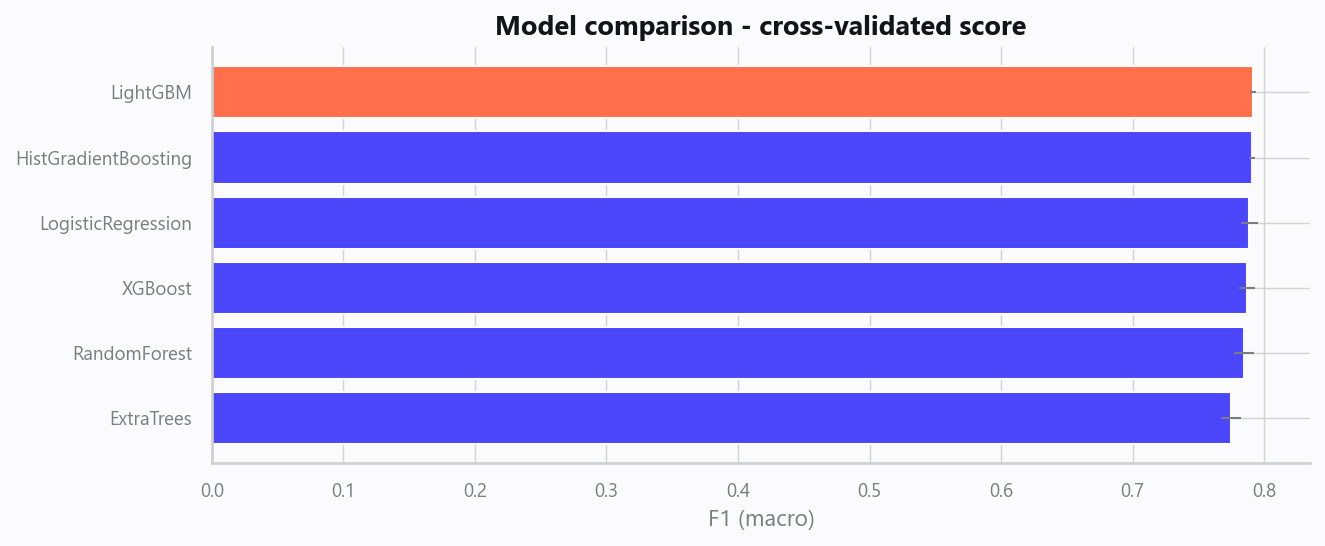
The engagement modelled the target 'Transported' as a classification problem in the Generic / Auto-detect (any tabular dataset) domain, using 8693 records across 14 columns (data source: train.csv). The pipeline audited data quality, engineered features, split the data honestly into train/test, and compared several models by cross-validation.
Outcome
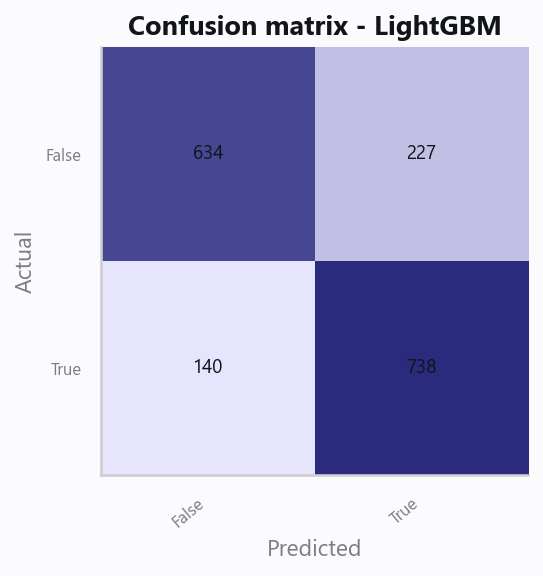
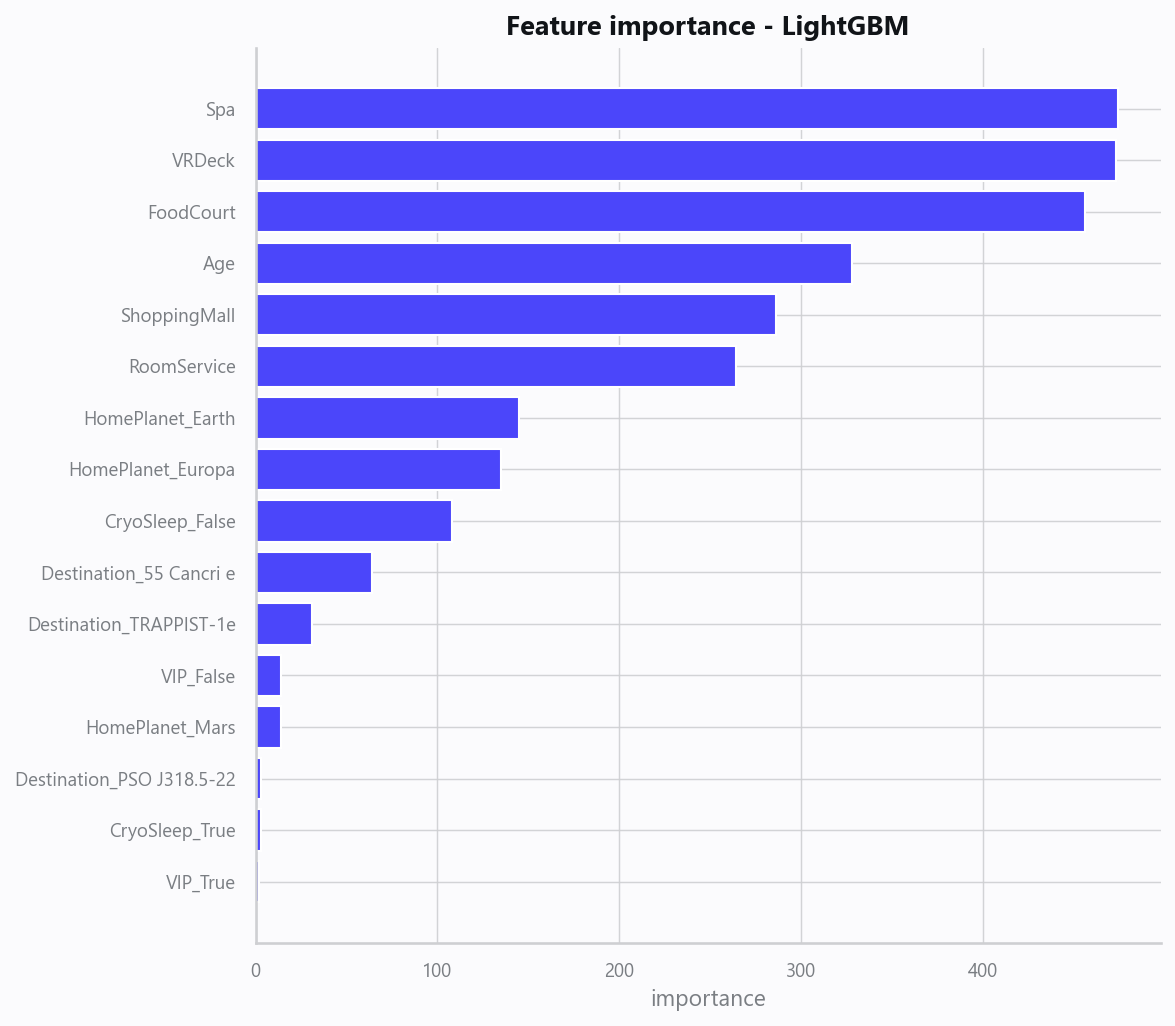
The selected model was LightGBM, with f1_macro = 0.7882 on the held-out test set. Supporting metrics: accuracy=0.789, balanced_accuracy=0.788, precision_weighted=0.792, recall_weighted=0.789, f1_weighted=0.788, precision_macro=0.792, recall_macro=0.788, cohen_kappa=0.577, matthews_. Full results, the deployment gates and the audit trail are in the run's report.
Figures
Artifacts
Data source: train.csv
Download report (.docx)Audit SHA-256: 80b6a9cecb8433c77be0dd7f0622a557016e500d06ccee4e5cdcc490a2682f50